The Fluent Plan Problem
A product lead sends you a Slack message on a Tuesday: "Can we do some research on why people aren't sticking around after onboarding?" That's the whole brief. No decision attached, no deadline, no idea who "people" are.
Five years ago you'd open a blank doc and spend the afternoon on it. These days you paste the message into an AI assistant, and thirty seconds later you have a study plan with objectives, research questions, twelve semi-structured interviews, a screener outline and a discussion guide. It reads well. It has the right headings. You could send it to the product lead within the hour.
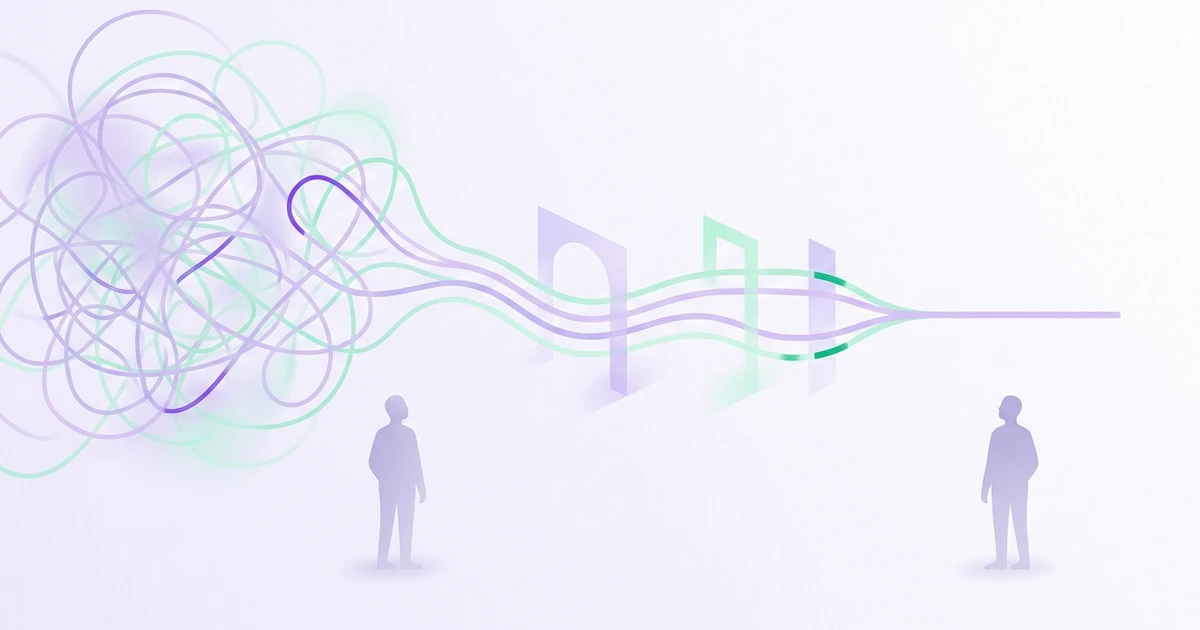
We call this the Fluent Plan Problem. When the plan reads well, people assume it is sound. A vague question goes in, a confident document comes out, and nobody notices that the vagueness is still there. It has just been covered up. The plan answers the question as asked, and the question as asked was never the real one.
This matters because the study plan is where most research quality is decided. You can't fix a badly framed study with great moderation or careful coding. If the plan targets the wrong decision, twelve excellent interviews still produce a readout nobody can act on.
Why AI Makes the Vague Question Look Finished
The causal chain is worth being precise about, because the fix depends on it.
First, language models resolve ambiguity silently. Faced with "why aren't people sticking around," a model has to choose what "people," "sticking around" and "after onboarding" mean. It makes those choices without flagging them, and it picks the most statistically typical reading: new self-serve users, 30-day retention, the first-week experience. Your company might mean enterprise admins who never invite their team. The plan doesn't say it made a choice. It just goes ahead.
Second, method selection defaults to the median. Ask for a study plan and you'll almost always get interviews, because interviews dominate the text these models learned from. Sometimes that's right. Often the real question is behavioural ("where exactly do they drop?") and needs analytics review or a diary study, or it's evaluative and needs usability testing. The model picks the method that is usually chosen, which is not the same as the method this question needs.
Third, polish lowers scrutiny. A rough plan in your own notes invites argument. A formatted plan with numbered objectives looks settled already. Stakeholders approve it faster, and researchers edit it less. The quality of the prose ends up standing in for the quality of the thinking.
The same pattern shows up in ML engineering. A model can score well on a test set that has quietly leaked into its training data, and the problem only shows up in production, as described in this piece on eval set contamination. A fluent study plan is similar. It passes the reviews you run on it, because the reviews check format, not whether the framing is right.
What Goes Wrong Downstream
Here is a pattern we see often. A 30-person research consultancy got a brief from a fintech client about "understanding trust in the app." The AI-drafted plan proposed 15 interviews exploring trust perceptions, and the client signed off in a day. Three weeks later the readout was full of well-evidenced themes about security and transparency, and the client's reaction was: "We knew all this. We needed to know whether to launch the savings feature to under-25s."
The real decision had been sitting behind the vague brief the whole time. It was a go/no-go on one segment, and it needed a different sample, different questions and a different deliverable. Nobody asked, because the plan looked complete.
The costs add up:
- Wrong sample. Participants are recruited for the typical reading of the question, not the real one.
- Wrong method. Attitudinal interviews get used to answer behavioural questions.
- Unfalsifiable objectives. "Understand trust" can't come back with a clear answer, so it can't change a decision.
- Stakeholder scope creep. A plan with no firm decision anchor collects extra questions, which is the mechanism behind stakeholder question injection.
The fix isn't to stop using AI to plan. The blank page is a real cost, and AI is very good at getting you past it. The fix is to split the work into stages where the AI speeds each one up and you still make the decision at each one.
The Five-Stage Workflow
Stage 1: Problem Framing -- Make the AI Interrogate, Not Answer
Don't start by asking for a plan. Start by asking for questions. Give the AI the raw brief and tell it to list every ambiguity, every assumption it would have to make, and every decision the research could plausibly inform.
For the onboarding brief, a good framing pass comes back with things like: Which user type? Retention by what definition? Is this about a change in the numbers, or a level that's always been low? What will the team do differently depending on the answer?
Then you take those questions back to the stakeholder. This is the step that matters most, and it's a human conversation. The output is one sentence we call the decision anchor: "This study will inform whether we [specific action] for [specific segment] by [date]." If you can't write that sentence, you aren't ready to choose a method.
A useful test: ask the AI to write three different decision anchors that the brief could support, and have the stakeholder pick one. People pick between options much more easily than they describe what they want from nothing.
Stage 2: Method Selection -- Force a Comparison
Never accept the first method suggested. Ask the AI to argue for at least three candidate methods against your decision anchor, and for each one to state:
- What kind of evidence it produces (behavioural, attitudinal, evaluative)
- What it cannot tell you
- Minimum viable sample and timeline
- The main way it could mislead you
Laid out side by side, the choice gets much clearer. For "why do enterprise admins stall before inviting their team," you might find that five contextual interviews plus an analytics review of the invite funnel beats fifteen open interviews. You also want to know what each method can't do. A plan that doesn't say what it can't answer isn't defensible.
Be especially careful when the AI suggests synthetic participants as a shortcut. They're useful for piloting a guide, but they can't stand in for evidence, for the reasons we set out in the Plausibility Trap.
Stage 3: Drafting -- Let the AI Do the Volume Work
This is where AI earns its keep. Once the anchor and method are fixed, have it draft the screener, the discussion guide, the consent language, the analysis frame and the timeline. Give it constraints: the decision anchor, the segment definition, the time budget per session, and the three or four things you must learn.
Ask it to tag every guide question with the objective it serves. Any question that can't be tied back to the decision anchor gets cut. That one rule keeps a guide much tighter than general advice about focus.
Stage 4: Revision -- Adversarial, Not Cosmetic
Most people revise AI drafts by tidying the wording. That's the least useful edit you can make. Revise by attacking the plan:
- Ask the AI to red-team its own draft. "Assume this study finished and the stakeholder said it was useless. Give three likely reasons." It's surprisingly good at this when asked directly.
- Run a leading-question audit. Have it flag every question that presupposes an answer or telegraphs the hypothesis.
- Check the screener for guessability. If a motivated participant could work out which answers get them in, the sample is compromised before the study starts.
- Simulate the readout. Ask for a mock one-page finding for each plausible outcome. If every outcome leads to the same action, the study won't change anything. Rethink it or cancel it.
We cover the launch-side version of this risk in the One-Click Launch Problem. Revision is the stage that makes sure you never ship a guide just because it looks finished.
Stage 5: Confirmation -- Close the Loop With Humans and Data
Confirmation has two parts, and people skip both.
Stakeholder confirmation. Send the decision anchor, the method rationale and the "what this cannot tell you" section to the stakeholder. Don't send them the whole guide. Ask them to confirm in writing that a result from this study would change what they do. This takes ten minutes, and it's the best protection you have against a readout that gets shrugged off.
Pilot confirmation. Run two or three sessions and treat them as real data about the plan. Where did participants misread questions? Which objectives got nothing? The first interviews often give the clearest signal about whether the framing holds, which is why we argue against discarding pilot data. If the pilot shows the framing is wrong, go back to Stage 1. Don't patch the guide.
Where the Researcher Must Stay in the Loop
It helps to be clear about which jobs belong to whom.
AI is strong at: listing ambiguities, generating method alternatives, drafting at volume, spotting leading language, red-teaming, and producing mock outcomes.
The researcher has to own: choosing the decision anchor, making the method trade-off, judging whether the sample fits the organisation's actual users, the stakeholder conversation, and deciding whether pilot evidence means you revise or reframe.
The dividing line is judgement about context the model can't see: company politics, the history of past studies, what the product lead actually meant. If you give that away, the result is a plan that looks right and misses. The Research Guide in Qualz.ai is built around this split. It walks you through framing, method comparison, drafting, revision and confirmation as separate checkpoints, and at each one it asks you to make the call before moving on, instead of producing a finished plan in one pass. The blank page goes away, and the decisions stay with you.
A Quick Before-and-After
Before (one-shot AI plan): "Objective: understand why users churn after onboarding. Method: 12 semi-structured interviews with recent users. Questions: How was your onboarding experience? What would make you use the product more?"
After (five-stage plan): "Decision anchor: whether to replace the self-serve admin setup with a guided call for accounts over 50 seats, decided by end of Q3. Method: 8 contextual interviews with admins who stalled before invites, triangulated with funnel data on invite completion. Cannot tell us: whether end users would adopt once invited. Pilot: 2 sessions, reframe if admins say invites were never their responsibility."
The second plan is shorter and less impressive to look at. It's also the one you can defend when someone asks why you did it this way.
Practical Takeaways
- Never ask AI for a plan first. Ask it for the ambiguities and assumptions hidden in the brief, then settle them with the stakeholder.
- Write a one-sentence decision anchor before choosing any method. No anchor, no study.
- Force a three-method comparison that includes what each method cannot tell you, and put the chosen method's limits in the plan.
- Tag every guide question to an objective and cut anything that doesn't trace back to the decision anchor.
- Revise by red-teaming, not rewording. Ask why the finished study might be useless, and mock up the readout for each possible outcome.
- Get written stakeholder confirmation that a result would change their action before recruitment starts.
- Treat the pilot as a test of the framing. If it breaks the framing, go back to Stage 1 instead of patching the guide.
If your team is stuck at the blank page, or keeps delivering studies that answer the wrong question, we'd be glad to show you how the Research Guide structures this workflow. Book a Qualz.ai information session and bring a vague brief with you. We'll turn it into a plan you can defend.